AI Use Case Canvas
- Use when
- Someone wants “an AI feature” and nobody has said what decision it improves
- Output
- The canvas — prediction, judgment, action, outcome, input, feedback — a simpler-fix check, a data check, and a verdict
· 9 min read · 36 skills, free
It starts before the model: does this need AI at all, and which mistakes would matter. Then the spec written as tests, the prompt and the agent's limits, evals built from real outputs, red teaming and launch gates, and the weekly transcript read that keeps it honest.
01What these skills are
This is AI product management that starts from the mistakes the feature can make, not the demo: Claude drafts the spec, the evals and the briefs, and a person who knows the domain makes the call.
The skills follow the job in seven stages, from asking whether a model is needed at all to what it costs and how to explain it to leaders.
The red line: Claude drafts the tests, never the verdict. It does not set the error your users can live with, sign off a launch, or report a score it did not see run on real outputs, and a person who knows the domain reads real transcripts every week.
Each skill is one named method or one artifact you walk away with, and ends with the decision a named person makes. It works from what you paste, with no eval platform to buy.
Legal, privacy and regulatory points become questions for a qualified adviser rather than answers. The sources behind each method are in resources/evidence-and- sources.md.
One zip: ready-to-install skill zips, readable SKILL.md files, and the sources behind every method. Free, no signup. The same 36 skills live in our open repo, if you would rather read them before you install them.
Install in Claude Code
Two lines, and every skill in the pack loads at once.
/plugin marketplace add polar-bear-org/claude-skills
/plugin install ai-product-managers-pack@polar-bear-skills
Using Claude on the web instead? Download the zip above and upload each skill from its install folder under Customize → Skills.
02The catalog
The set follows the work, in seven stages: deciding if AI fits, speccing it, briefing the model and the agent, building the evals, shipping it safely, running and improving it, then cost, price and explaining it.
03How to use it
No fixed order. Bring one live piece of work and open the skill that matches where it is stuck.
Someone asked for “an AI feature”.
The feature needs a spec you can test.
The system prompt grew by patches.
You have real transcripts and nothing to measure them with.
Launch is close and it needs gates that can stop it.
The feature is live.
Finance, legal and leadership have questions.
04Setup guide
In Claude Code · two lines
/plugin marketplace add polar-bear-org/claude-skills
/plugin install ai-product-managers-pack@polar-bear-skills
In Claude.ai or Claude Desktop · seven clicks
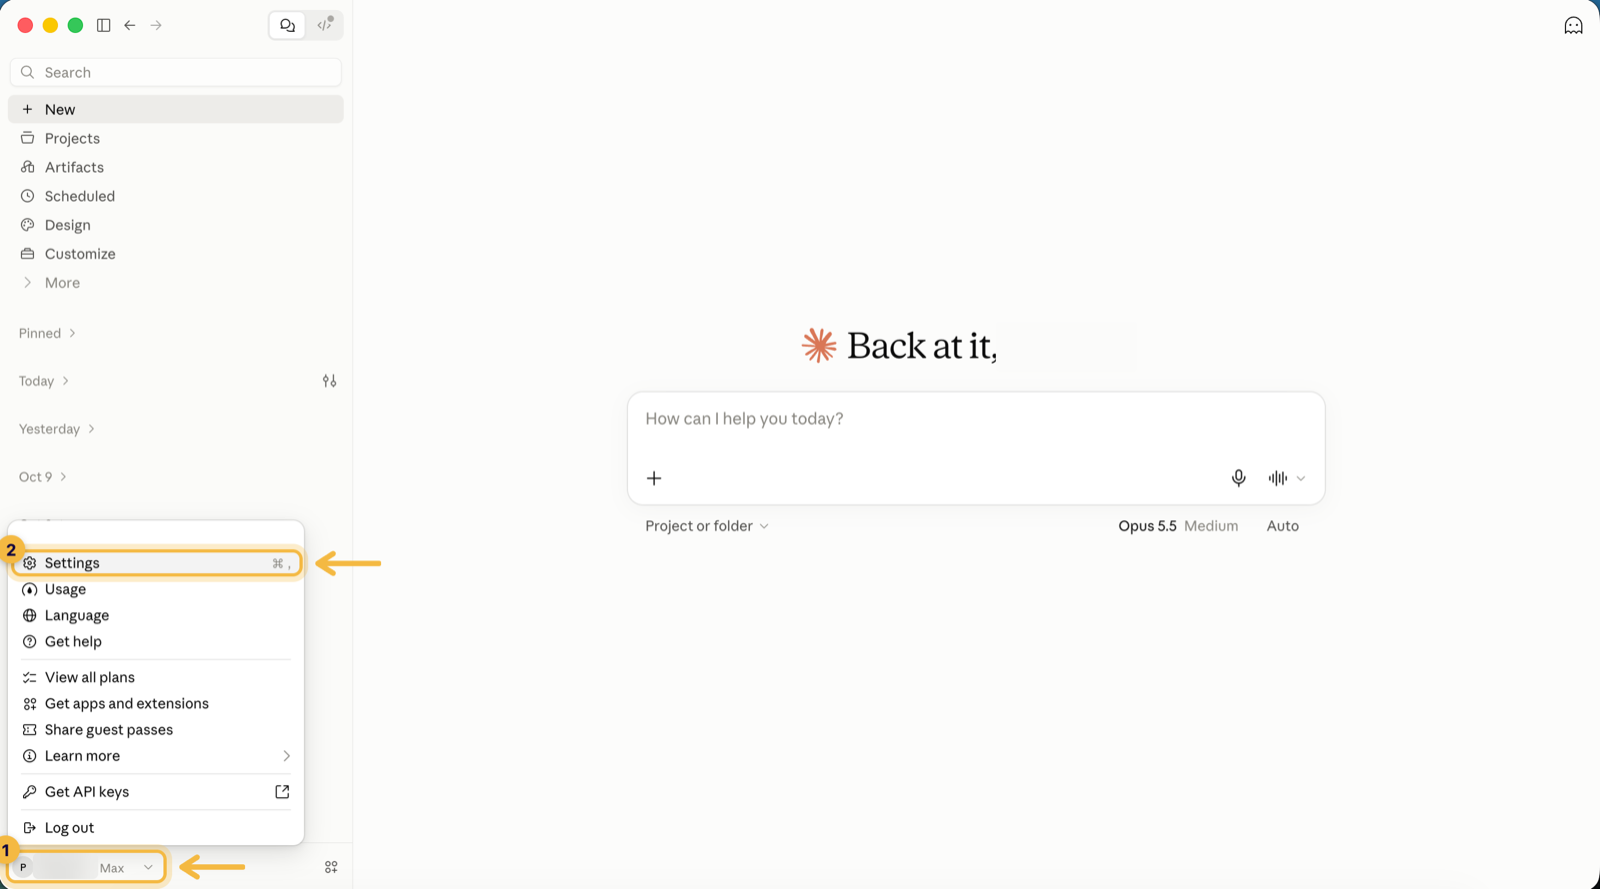
Unzip the pack: its skills folder holds all 36 skills. In Claude, click your name at the bottom left, then Settings.
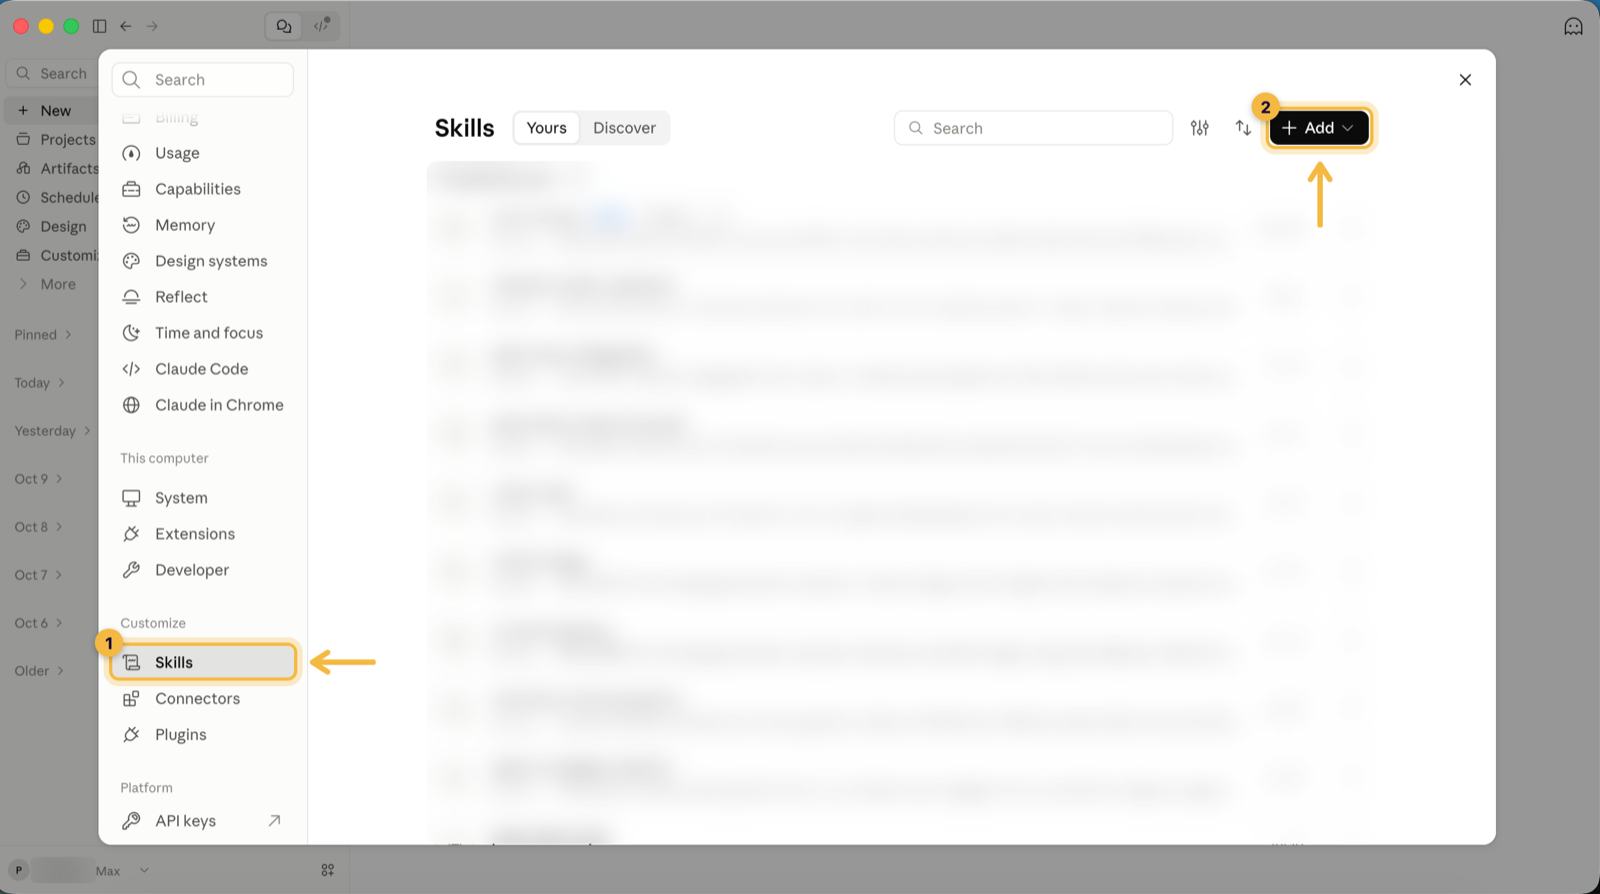
Under Customize, choose Skills. Click Add, then Upload a skill.
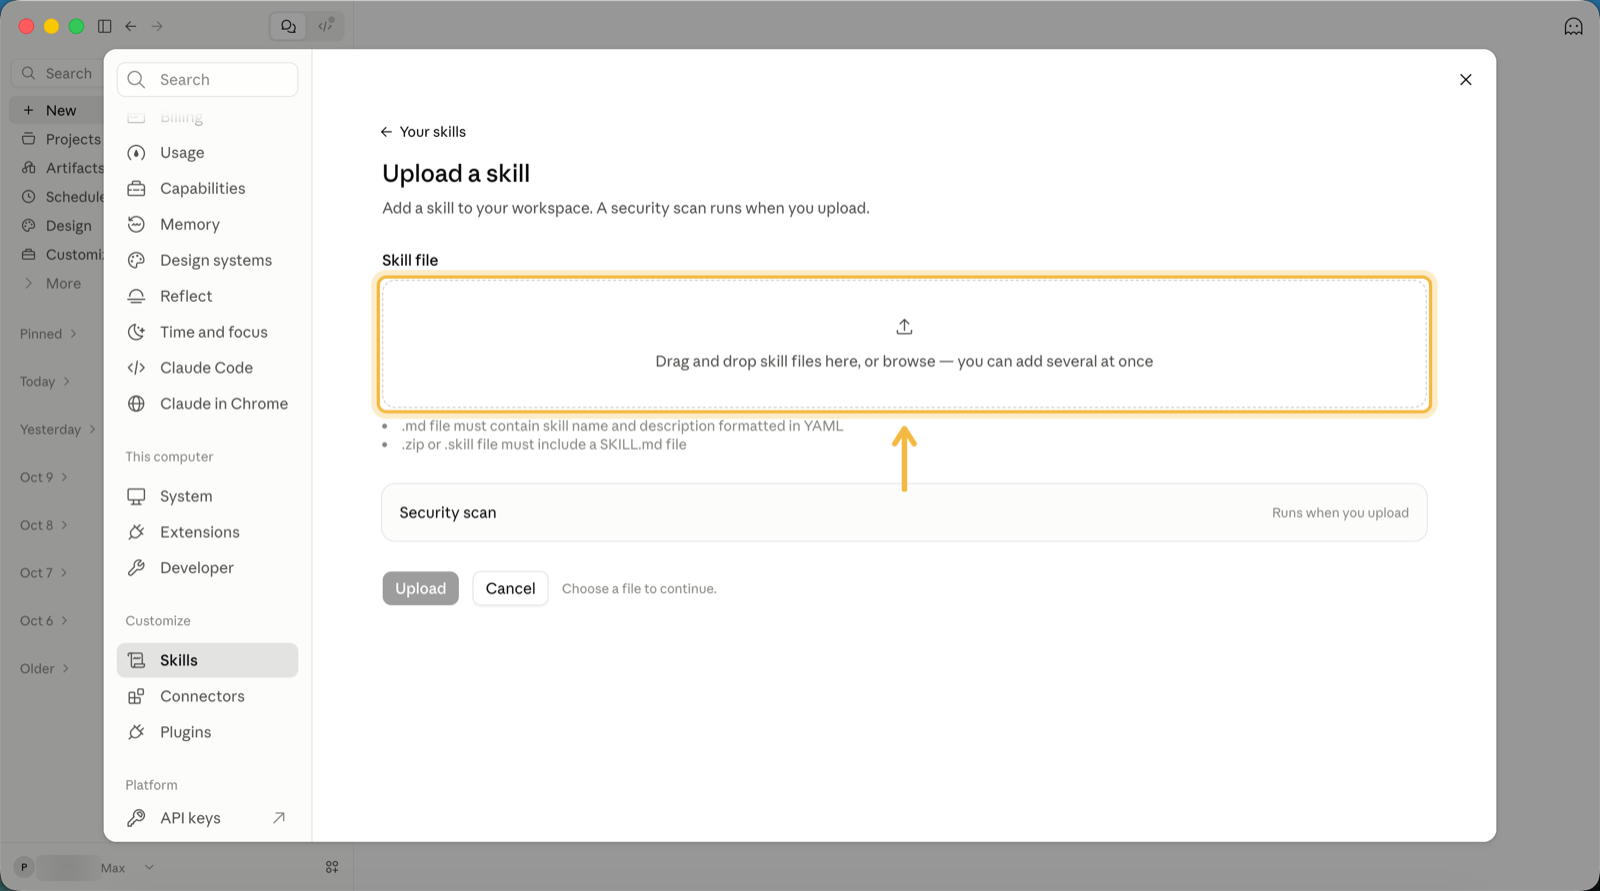
Drag the skill's file into the box, or click to browse. You can add several at once.
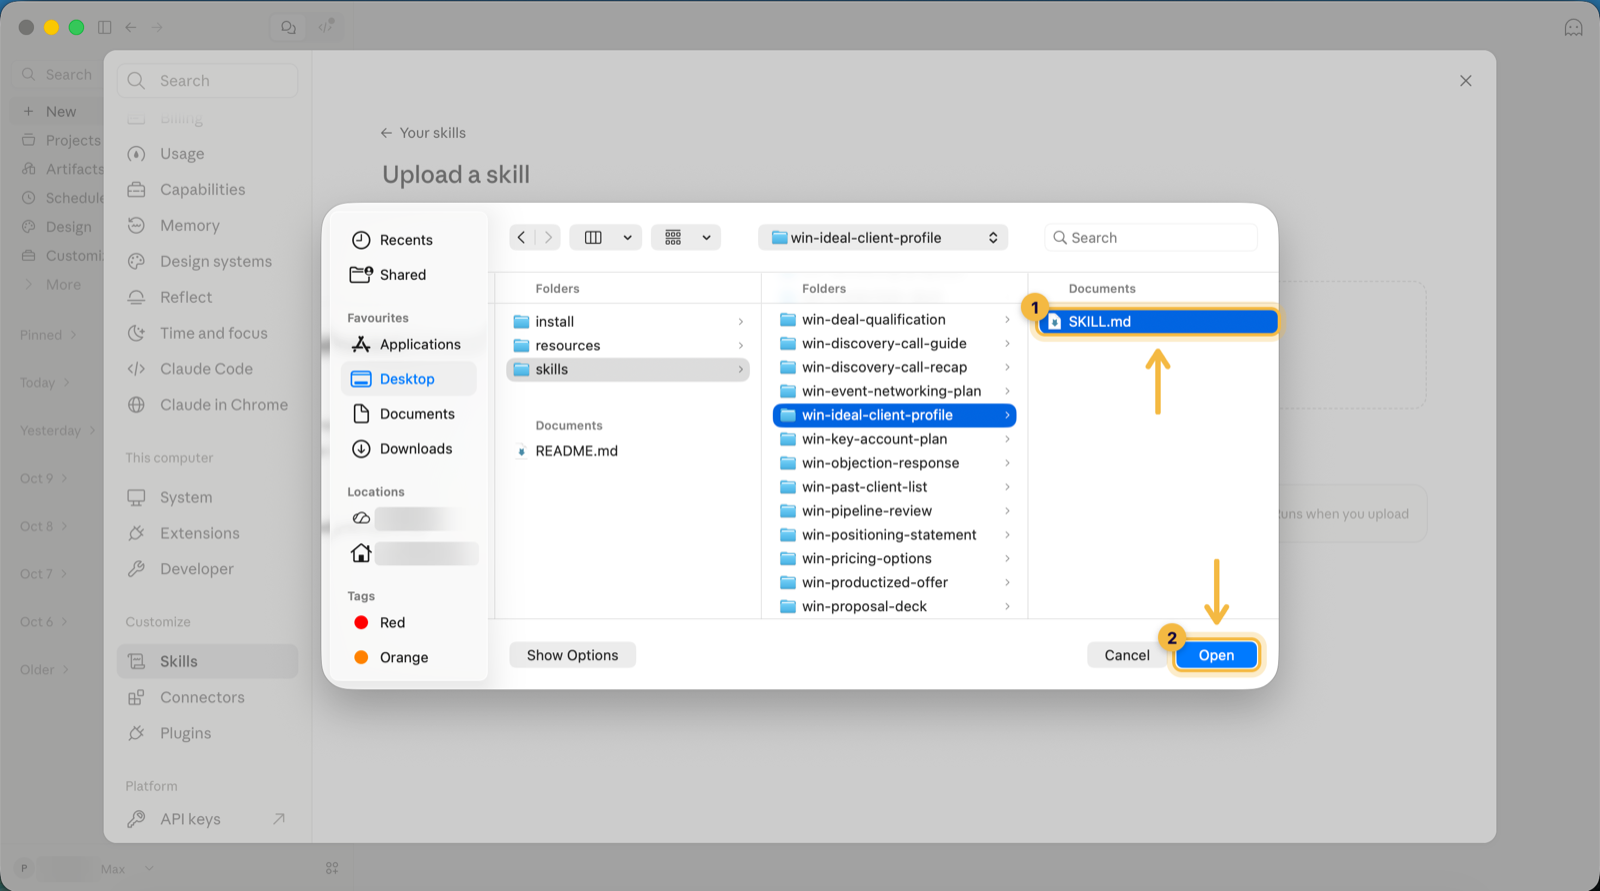
In the pack folder, open skills, then the skill you want, and select its SKILL.md — aipm-ai-use-case-canvas is a good first one.
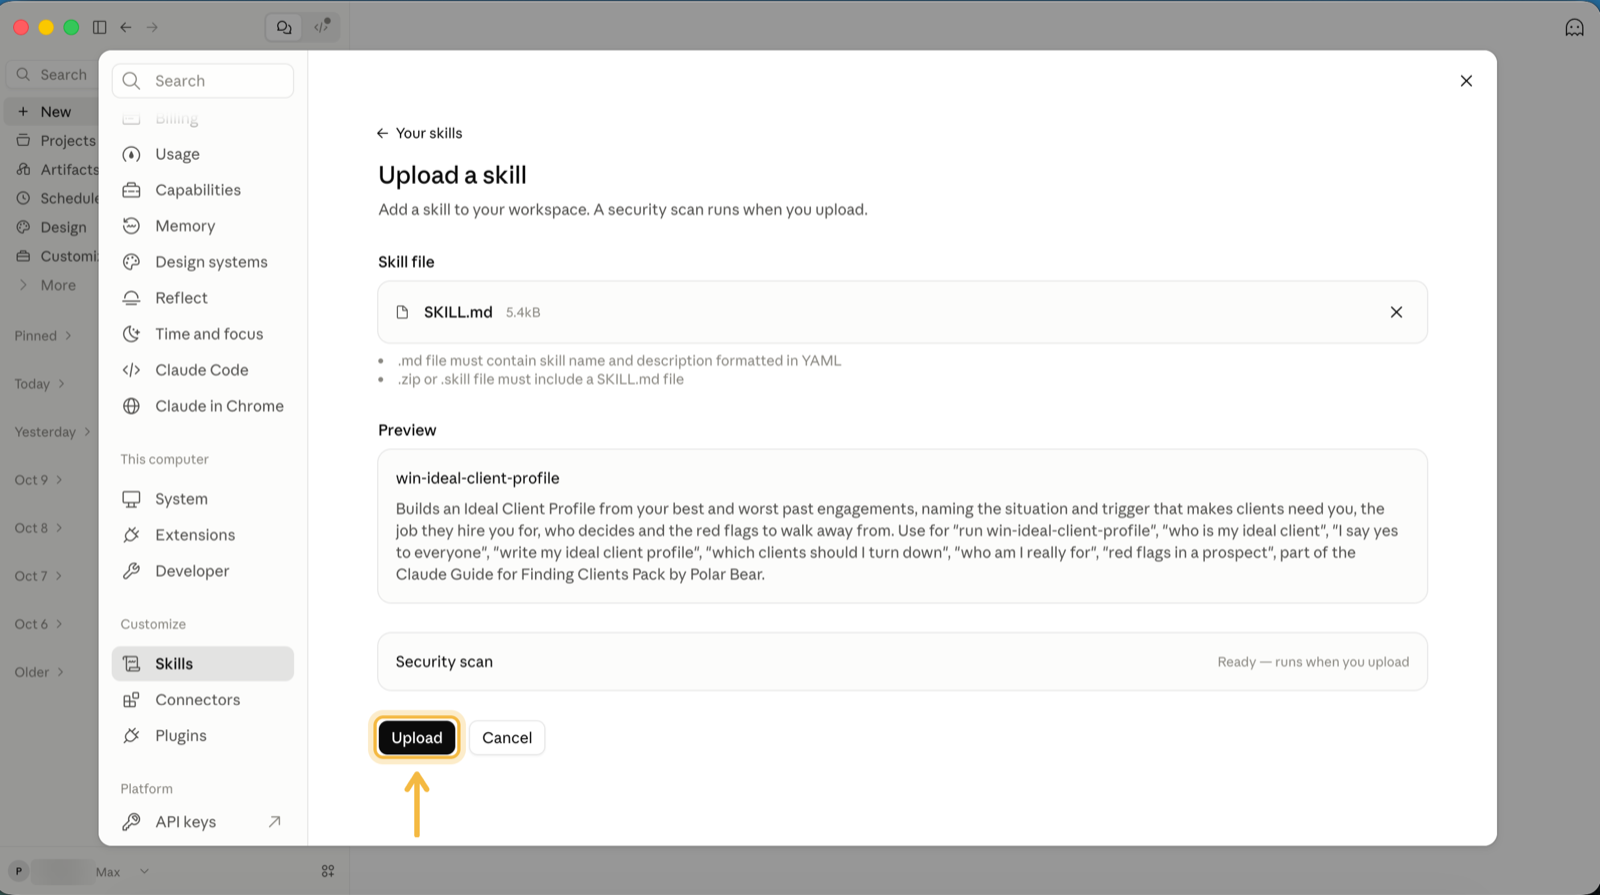
Claude shows the skill's name and what it does. Click Upload.
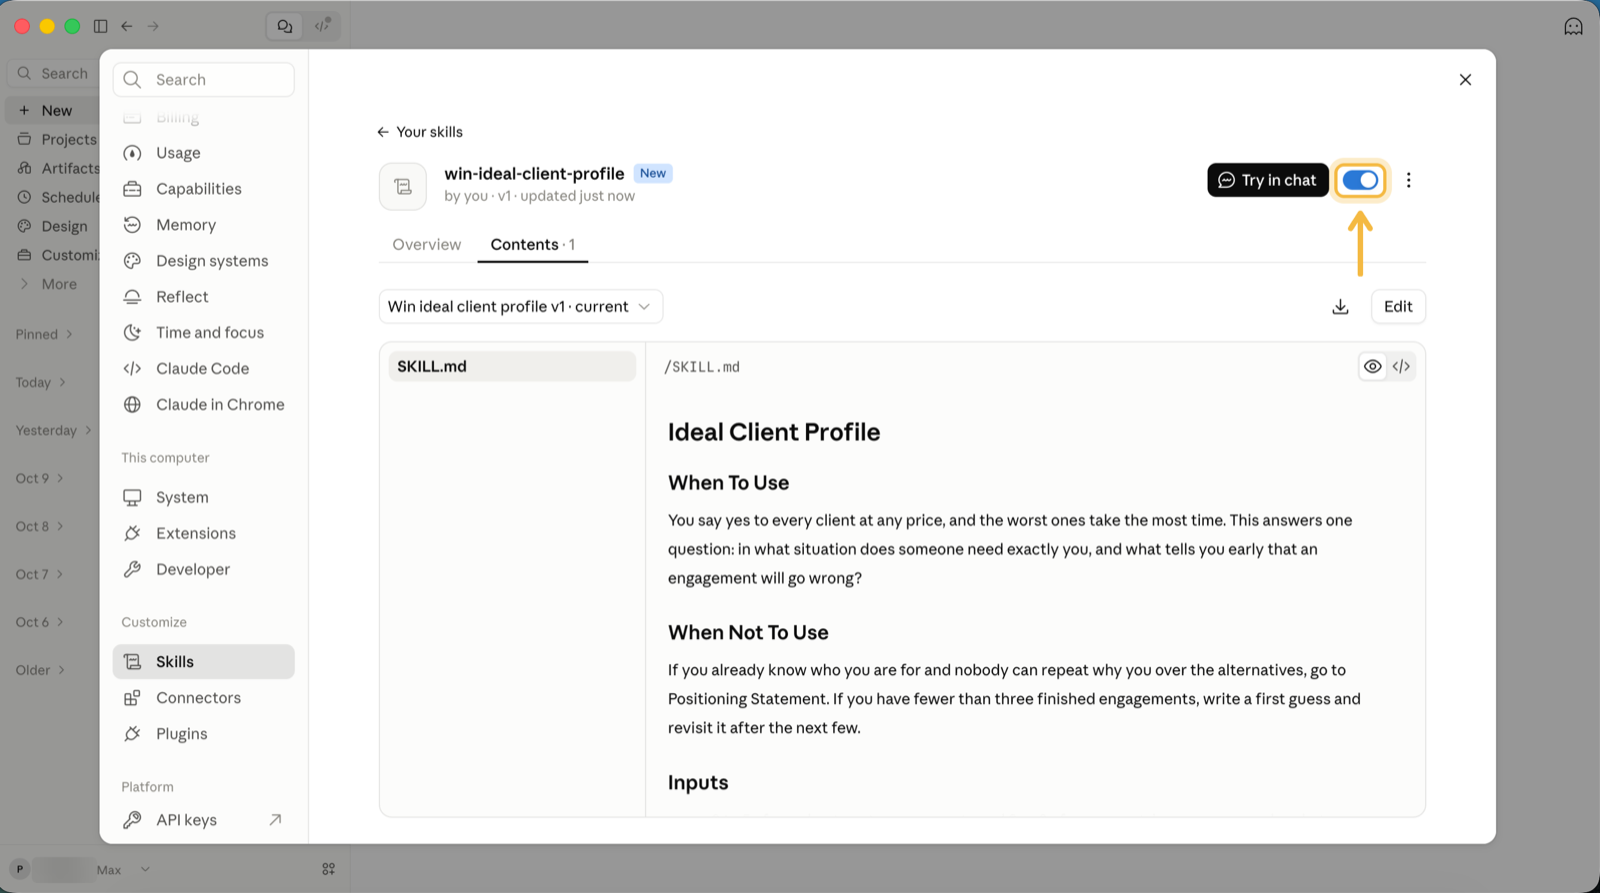
The skill opens on its own page. Its toggle should be on.
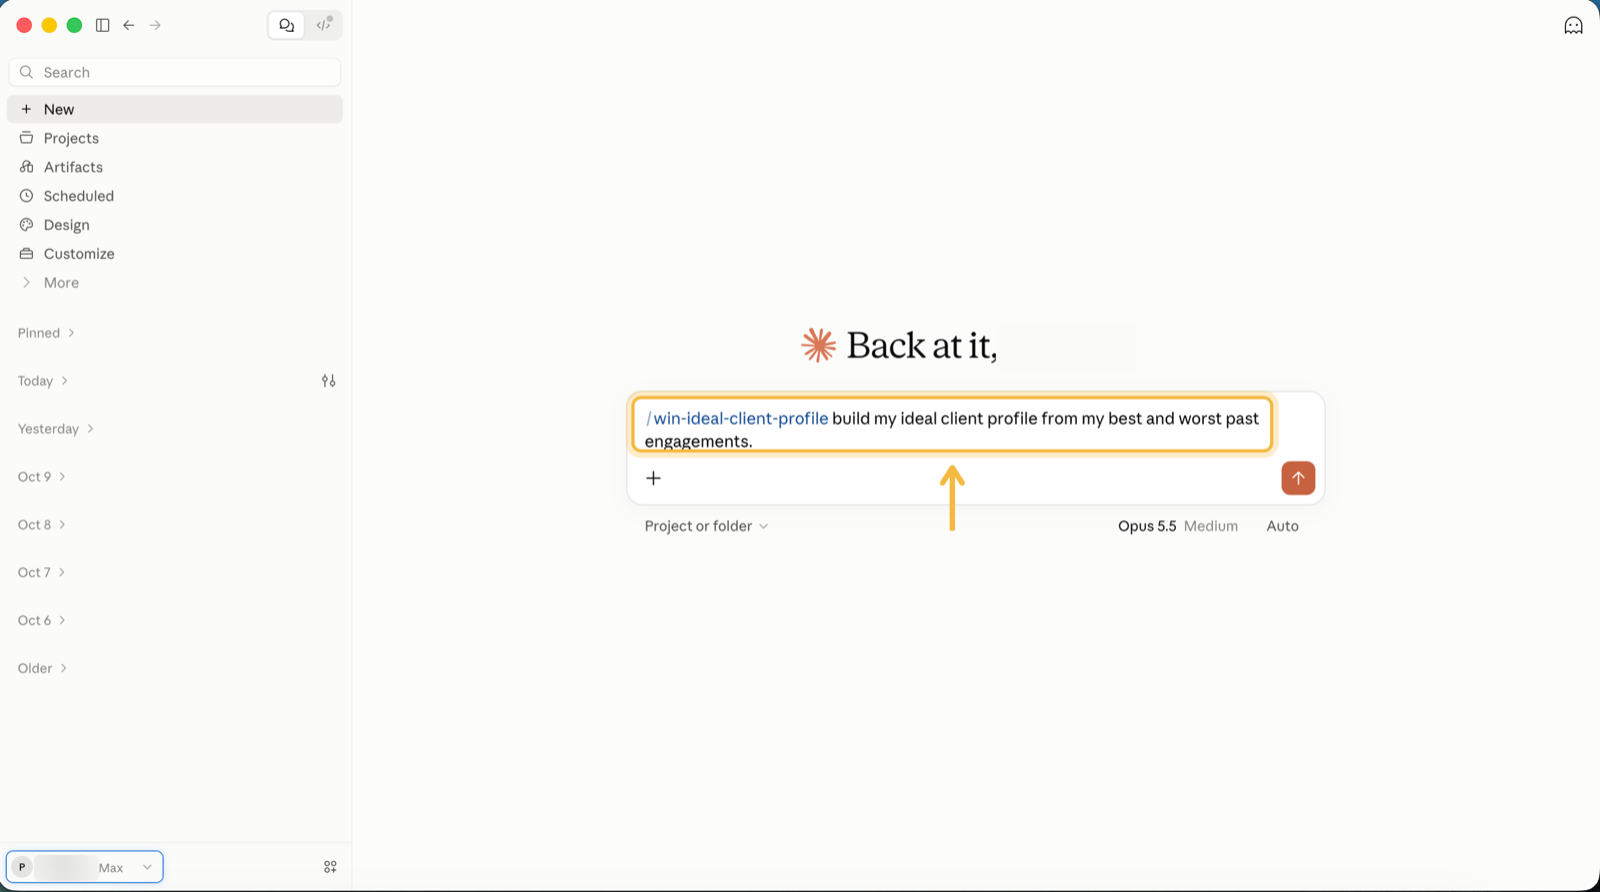
Type / and the skill's name, then say what you need.
Then try one
Run aipm-ai-use-case-canvas on this request for an AI feature: [paste it here]
Run aipm-system-prompt. The system prompt as it stands: [paste it here]
Run aipm-error-analysis on last week's transcripts: [paste them here]


Lantern for AI product managers
Turn what you learned testing an AI feature into posts
Lantern drafts a week of posts from your notes and call transcripts, in your voice. You review them and publish the ones you like.
100 free credits, about ten posts. No card needed.
Try for free05Quick reference
| Your situation | Skill to run |
|---|---|
| Need to know if a model is needed at all? | AI Use Case Canvas |
| Need to show which mistakes matter? | AI Failure Modes Map |
| Need to choose between a workflow and an agent? | Workflow or Agent Decision |
| Need a demo not mistaken for the product? | AI Prototype Brief |
| Need a spec engineers can test? | AI PRD |
| Need “good” written as numbers? | AI Success Criteria |
| Need limits an agent cannot cross? | Agent Spec |
| Need failure types from real outputs? | Error Analysis |
| Need a test set built from real cases? | Golden Dataset |
| Need to attack it before strangers do? | AI Red Teaming Plan |
| Need to know a prompt edit broke nothing? | Prompt Regression Test |
| Need cost per successful outcome? | AI Unit Economics |
06Standards
Every skill in the pack holds the same standard, the one we hold when we ship AI in our own product:
07FAQ
36 Claude skills that follow AI product work in seven stages: decide if AI fits, spec it, brief the model and the agent, build the evals, ship it safely, run and improve, and cost, price and explain. Each skill is one named method or one artifact.
In Claude Code, two lines install all 36 at once. In Claude.ai or Claude Desktop, download the zip, open Settings, Skills, Add, and upload the skills you want. Either way it takes about five minutes.
No. The skills work in Claude.ai, Claude Desktop and Claude Code. In the app you upload them yourself; in Claude Code one command installs the whole pack.
They are built as Claude Skills, and installing them is a Claude feature. Each one is a plain Markdown file, so you can read it and reuse the method elsewhere, but it will not load and trigger by itself outside Claude.
No. Claude drafts the tests, never the verdict. It does not set the error your users can live with, sign off a launch, or report a score it did not see run on real outputs. A person who knows the domain reads real transcripts every week.
Yes. It is free to use inside your company and in client work, and not for resale. There is no signup: the download and the install command are on this page.
08Who made this
These skills were written by Polar Bear, a people ops consultancy that runs its own company on Claude. The pack is free, and the same skills are open on GitHub.
Lantern is Polar Bear's content workspace. It turns your notes, documents and call transcripts into drafts for LinkedIn and other networks. You review them and publish the ones you like.